AI Content Creation Starts with Better Topic Discovery
Cross‑border e‑commerce teams often first organize product images, specifications, discounts, and brand introductions, then let AI generate Instagram, TikTok, or YouTube copy in bulk. The results usually appear quickly, but the content reads like a rephrased product detail page: fluent, complete, and free of obvious errors, yet it doesn’t address the problems users are trying to solve.
These reworks often surface only after publishing. Operators notice low click‑through rates and then go back to examine the topic; they then re‑search keywords, rewrite the tone, add market information, and send it through translation and review teams again. Generation speed has increased, but content effectiveness has not kept pace.
The effectiveness of AI‑generated content first depends on whether the topic stems from real demand, concrete scenarios, and a clear platform context. A safer workflow is to discover user problems, then filter by market and channel, define the content task, and finally let AI expand angles, rewrite expressions, and schedule distribution. This reduces ineffective generation rather than simply boosting volume.
Poor AI Content Performance Is Usually Not a Writing Issue but a Topic Input Issue
AI content generation excels at expanding, rewriting, summarizing, and organizing existing information. It can turn a set of product selling points into a short article, script, or social media post, but it won’t automatically decide whether consumers care about the issue just because the product data is detailed enough. When the input lacks a demand basis, even the smoothest output is just a slick packaging of the original material.
Input problems are more complex in cross‑border e‑commerce. The same product, different markets, and completely different user concerns: German shoppers may first ask about return procedures and warranty periods, U.S. users care more about delivery speed, while Southeast Asian markets may repeatedly inquire about payment methods, tariffs, and local after‑sales service. Language differences are superficial; holidays, logistics, payment habits, and platform cultures all reshape the search intent behind keywords.
Many teams mistake “there’s something to write about” for “it’s worth writing continuously.” Product data can provide material, functions, discounts, and usage methods—enough to support an introductory piece. But sustained production depends on whether the audience repeatedly discusses related issues, whether there are scenarios not yet clearly explained, and whether the brand has evidence to present viewpoints different from competitors. A topic that relies only on internal product data quickly becomes repetitive promotional copy.
In 2024, a cross‑border team generated content in bulk before a major promotion. Operators used the same set of selling points to prepare posts for ten platforms, making only minor rewrites to fit each platform’s character limits. Two weeks after publishing, the team discovered that the most sensitive market for the product was installation and after‑sales service, not discounts. Consequently, translation, rewriting, review, and content calendar scheduling all had to be redone, and the material that had been prepared early consumed almost another week of operational time. Generation was fast, but it didn’t make the topic more effective; instead, it amplified the error across more channels.
The more platforms you use, the easier it is for such bias to be hidden. Ten platforms are not just ten publishing entry points; they have different content lengths, interaction styles, recommendation mechanisms, and audience expectations. A keyword suitable for a search explanation isn’t necessarily fit for a short‑video hook; a controversial post that garners many comments on social media may not be suitable for a brand advertisement. Topics must be evaluated together with channels, not assessed in isolation from the publishing context.
Wrong topics also create a false sense of busyness. Teams produce new copy, new versions, and new schedules daily, but reviewers keep pointing out missing facts, market leads keep demanding new angles, and designers keep re‑matching assets. In the end, content reuse does not reduce cost; it merely spreads a theme lacking a demand basis more widely.
Discover Topics from Real Discussions First, Then Let AI Expand Angles
Cross‑border teams can break topic discovery into three actions: “discover → decompose → filter.” Discovery means finding what users are currently discussing; decomposition means turning the discussion into questions and scenarios; filtering means judging whether the brand has the qualification, evidence, and channel to respond. AI can help organize and expand, but it should not skip the first two steps and turn a hot word directly into a post.
During the initial screening, observe at least three types of signals:
- Repeated user questions: the same issue appears continuously in comments, forums, or customer service records.
- Rising industry discussion: the keyword’s frequency and interaction in news, videos, or communities increase noticeably.
- Content gaps in the category: competitors have covered feature descriptions but not explained installation, comparison, after‑sales service, or real‑world limitations.
A topic must satisfy at least two of these signals to merit the next step. A single keyword’s popularity isn’t enough, as it may stem from a one‑off news event; a single user question isn’t enough, as the issue might belong to a tiny usage scenario. When two signals intersect, the topic is more likely to have lasting content value.
A practical approach starts with product keywords and checks Reddit, YouTube, news, and Hacker News. Operators should not only record titles or likes but also preserve original sentences from discussions, the question background, recurring concerns, and the user’s phrasing. For example, a product description might say “lightweight outdoor equipment,” while users search for “can I bring it on a plane,” “will it break in rain,” or “can one person install it quickly.” The latter is closer to an actionable content topic.
Raw discussions need to be organized into topic cards, not directly copied as hot topics. A card should contain at least the audience’s question, specific scenario, provable viewpoint, and suitable platform. This also has a side effect: expression differences across markets become new content angles rather than translation burdens. One market may discuss “delivery promises,” another “return hassles,” which does not mean one version is wrong; it indicates that product content must be reorganized according to local transaction risks.
In practice, teams should place external discussions and publishing conditions in the same record. Social‑media trend data can serve as background reference for the content operations workflow, e.g., View social platform trend data, but trend‑page popularity does not equal a brand’s direct follow‑up reason. If content is to be posted on TikTok, teams should also check the TikTok platform development rules for publishing permissions, media formats, and API limits, avoiding the situation where a topic passes filtering only to discover the channel cannot support it as planned.
To further simplify the publishing workflow, teams can consider adopting the End of manual social publishing era for automated scheduling and cross‑platform sync.
Before a topic card enters production, four questions are usually asked: why is the user caring now, what evidence can the brand provide, which judgment should the content change, and on which platform should that judgment occur. Only then does AI have a sufficiently clear scope to generate explanations, comparisons, demonstrations, or responses, rather than freely riffing on a product name.
Topic Validation Must Consider Demand, Differentiation, and Platform Fit Simultaneously
Pre‑publish validation can be divided into three layers. The first looks at demand, confirming that the topic addresses a concrete problem rather than an internally assumed “selling point.” The second examines differentiation, ensuring the brand can supply real measurements, data, case studies, processes, or explicit limitations. The third checks platform fit, confirming that the issue can be naturally expressed in the target channel rather than forcing a long explanation into a few paragraphs.
Before AI generation, the content task must also be defined. Educating users, addressing doubts, showcasing usage scenarios, and driving product comparisons each require different structures. If the task is simply “introduce a product,” AI will easily spread specifications, advantages, and discounts evenly; if the task is “help first‑time buyers decide if it’s suitable for long‑distance travel,” the output will focus on luggage limits, range, installation, and after‑sales evidence.
In workflows that aim to reduce copy‑pasting, tab switching, and multi‑platform scheduling friction, Flownib appears at the publishing and recording layer: operators first prepare a verified core topic, then hand the platform‑specific formats to the system. Connecting may take about two minutes, but that is only tool configuration time and should not be mistaken for a two‑minute topic‑validation process. Topic sources, market rationale, and review records still need to be retained by the team.
The same core topic can be turned into multiple content angles, but it should not be limited to swapping a few emojis in the same copy. For example, the topic “overseas users worry about return hassles” can become a full return‑process guide on YouTube, a common‑misconception hook on TikTok, a specific‑scenario answer on Reddit, and a cross‑border after‑sales management experience on LinkedIn. The theme stays consistent, but evidence order and narrative style must be redesigned.
When price, logistics, inventory, warranty, and performance promises are involved, review is especially prone to underestimation. AI may reuse outdated promotional prices or write a country‑specific delivery time as a global promise; after translation, a cautious “may apply” can become a definitive statement. Reviewers should verify factual accuracy, market context, price and logistics information, and sensitive promises item by item, keeping evidence traceable to the original data rather than merely checking if sentences sound natural.
If a team is reorganizing accounts, permissions, content calendars, and publishing methods, they can also refer to the discussion on Integrated social media tool selection regarding account management and platform differences. Tools can shorten operational paths but cannot decide whether a topic deserves the brand’s long‑term content resources. That judgment should still be written on the topic card, not hidden in a scheduler’s memory.
To compare API support across different tools, read the FlowNib vs Publer vs Planoly API comparison to determine which fits an omnichannel need.
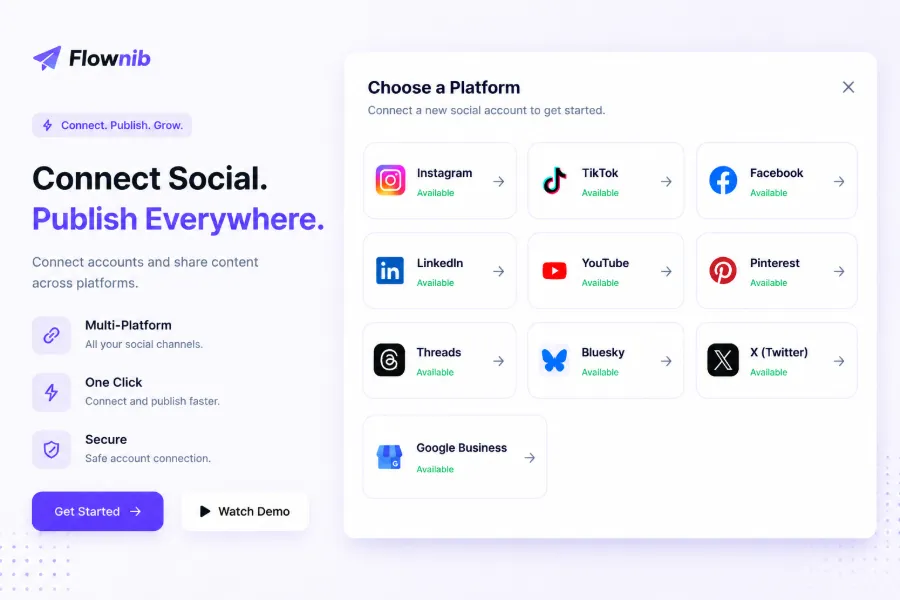
Another pitfall of cross‑platform publishing is interpreting “consistent brand voice” as “all platforms use the same sentences.” Brand voice can stay stable, but content angles should follow platform context. The more mechanical the platform adaptation, the more likely the content will be format‑correct but lack community feel; over‑adaptation can cause expressions in different markets to drift from facts. Operations teams usually need to repeatedly calibrate between consistency and naturalness, rather than aiming for a one‑shot perfect generation.
Turn Topic Discovery into Ongoing Review, Not a One‑Time Inspiration Search
Topic discovery should not end before publishing. Cross‑border e‑commerce teams can make the process a loop: “discover → generate → publish → observe → recycle.” First record the original discussion, generate platform versions, observe data after publishing, and finally feed performance and the original question back into the content library. The recycle is not a single successful copy but a validated audience problem, expression angle, and applicable market.
During review, group topics by market, language, product line, and platform. Looking only at a single piece’s exposure can easily mistake occasional platform‑driven traffic for stable demand. Clicks, saves, new questions in comments, conversion paths, and production time should be viewed together. Some topics have low exposure but generate high‑quality inquiries; others generate many comments that revolve around controversy and hardly lead to product pages. These two outcomes cannot both be labeled “good performance.”
A team once chased a short‑term hotspot for three weeks, pushing high‑engagement feedback from one market to global accounts. In the second week, other markets’ click rates fell, and comment sections filled with doubts about local logistics and pricing. The team had only looked at exposure until ad attribution and customer‑service issues rose, revealing that the content library lacked the original topic source and did not note that the theme only applied to a specific market. Later they kept the hotspot content but stopped global replication, instead splitting the problem and evidence by market.
Automation can reduce distribution friction but cannot solve topic judgment. Even if a system achieves 99.99 % API uptime, publishing may be stable while the topic still lacks demand and fails to drive conversion. Stable execution and content effectiveness are two different lines; the former only shows that interfaces, scheduling, and account connections are not broken.
Teams don’t need to keep producing every high‑engagement topic. Some topics require extensive manual fact‑checking; some markets carry high compliance risk; some content, while generating comments, attracts an audience unrelated to the product. The purpose of content review is not only to identify “what to keep doing” but also to clearly mark which topics to stop investing in, preventing the content library from being filled with short‑term spikes and low‑quality traffic.
When the topic library retains source, market, platform, evidence, results, and production time, AI can take on more specific expansion work. It can generate different angles from verified questions and help teams spot repetitive expressions, but it cannot replace the team’s decision on which problems deserve long‑term content resources. Better input still determines the ceiling of AI content work.
FAQ
Why does AI‑generated cross‑border e‑commerce content often read smoothly but lack real impact?
Because the input usually contains only product data, without clear user problems, market scenarios, and content tasks. Teams may generate dozens of pieces in a day, but if they don’t record clicks, comment questions, and conversion paths simultaneously, they often discover after one to two weeks that the topic has no demand.
Should topic discovery prioritize search keywords or social‑media discussions?
Both should be used in tandem, not with a fixed priority. Keywords are better for gauging actively searched demand; social‑media discussions more readily reveal real doubts and usage scenarios. A topic should only move to content validation when at least two types of signals appear together.
Can a topic be directly rewritten for different countries and platforms?
No, it cannot be copied directly; only the validated core question should be retained. Payment, logistics, holidays, and after‑sales contexts differ across countries, changing expression focus; different platforms also require adjustments to openings, evidence order, and length, so each market version should be reviewed separately.
What topic information must be prepared before letting AI generate content?
At minimum, prepare the audience question, specific usage scenario, target market, verifiable evidence, and suitable platform. If the content task (e.g., educate, compare, address doubts) is not defined, AI will likely produce generic product introductions again.
How to decide whether a hot topic is worth continuing to produce content for?
A hot topic must simultaneously present a recognizable audience question, a reasonable brand connection, and observable downstream behavior. Teams should review clicks, saves, comment quality, conversion paths, and production time after at least one round of publishing, rather than deciding solely based on exposure.
Share Article